
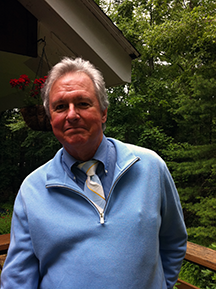
George Cobb bloomed early and ran to seed. Aspiring first to herpetology, he ascended through chemistry to mathematics, but then—having reached his apex but failing to accomplish much of anything by the age at which Galois died—he began his happy lifelong descent, through a fascination with Russian literature at Dartmouth (’68) and ever downward into statistics—an easier exegesis of texts written in numbers. Because of Fred Mosteller, he went to Harvard for his PhD (’74). He did his dissertation with Art Dempster and later learned much from David Moore, Dick Scheaffer, and his students at Mount Holyoke—the country’s oldest college for women. He is author or co-author of books, recipient of the ASA’s Founders’ Award, a former member of the NAS Committee on Applied and Theoretical Statistics, a former ASA vice president, and—as noted above—a former aspirant to commit a biological science and sit with serpents.
Thoughtful statisticians know what far too many users of statistical methods do not, the big and open secret that hides in plain sight: Inference from data cannot be reduced to rules.
To oversimplify, but only a little, the mistaken readiness of students and researchers to rely on rules in statistics has its roots in two sources: a natural human instinct and an intellectual error. The first source is our urge to understand by simplifying. We seek abstract patterns. There is survival value in remembering what works in general, ignoring irrelevant detail, and doing as much as we can without taking the time for unnecessary intellectual effort—so we can save that effort for when it counts most.
The second source of our reliance on rules in statistics is an intellectual error, a failure to distinguish between uncertainty and ambiguity. Uncertainty is easy: Our profession teaches that we can quantify uncertainty if we have a probability model. If the null model is correct, for example, we can compute the chance of getting data as extreme as what we actually observed. The devil, of course, is in the “if,” in the condition without which the p-value loses its usual, formal meaning. Too often, our teaching—and the statistical practice of those we have taught—fails to emphasize the importance of the “if.”
Worse, however, is our failure to teach the difference between uncertainty and ambiguity. Our teaching puts its focus on uncertainty because, as with the drunk searching for his keys under a street light, uncertainty is what our science allows us to quantify. But too often, just like the keys of the hapless drunk, the keys to sound inference lie hidden in shades of ambiguity. Ambiguity is hard.
- How were the data obtained? Do our data come from an observational study, rather than an experiment? Is the study cross-sectional or longitudinal, etc.?
- What about the analysis? Was the model chosen in advance or after the fact, as part of trying out several possible models? How did we decide which concomitant variables to collect? How did we decide which ones to include in our model and which ones to leave out?
- What about the conclusions? Are there plausible alternative explanations for the observed result (e.g., bias)? Is the effect size meaningful? Is there prior information that is part of the context? Are we engaged in basic research, or are we recommending a decision with costs and benefits that should be taken into account?
These and similar considerations are what I mean by “ambiguity,” as distinct from uncertainty. Uncertainty is easy; ambiguity is hard.
For those of us who care about the teaching of statistics, the biggest challenge posed by the recent ASA statement on p-values is the challenge of the role of ambiguity and context in data analysis. Many students come to their introductory courses expecting numerical recipes. Many are apprehensive about “formulas.” Many more expect formulas and rules like p < 0.05 to substitute for judgment. As much as formulas may make some students uncomfortable, to ask for judgments that can’t be reduced to rules will make them far more uncomfortable.
So much for what students will find hardest. Consider now the teachers, especially those teachers who have little experience with applied work in statistics. When it comes to statistical methods and probability concepts, research in statistics education has provided important insights into both common misconceptions and effective pedagogical innovations. The reforms of the last several decades have led to a host of textbooks for introductory courses that do a good job of explaining statistical methods for dealing with uncertainty and showing those methods in the context of actual applied problems. Teachers who are unsure of their background in statistics can learn as they teach from any of the good textbooks and ancillary materials.
The challenge is that we have no good models for helping students learn to think systematically about ambiguity as distinct from uncertainty. I suggest that this challenge offers a fruitful area for research—about the way students think about ambiguity in science, about what misconceptions they may have, about how practicing scientists think about ambiguity in their use of statistics, and about how we can develop effective strategies for teaching.
One simple place to start might be checklists. Several textbooks now offer checklists of assumptions for the probability models we use to compute p-values and confidence intervals (e.g., independence and normality of errors, constancy of effects and variances, etc.). This is a start, but only a start. (Books still too often teach that p-values are useful only for formal tests of hypotheses. The more careful books spend time on checking assumptions as part of the justification for formal inference, but we ought also to be teaching that p-values can be useful as descriptive statistics even when assumptions are not supported.)
The usual list for checking assumptions can serve as a model for other checklists related to ambiguity. Presumably, such lists would depend on applied context and vary from one applied field to another. There might be quite different checklists, for example, for clinical trials, for experimental work in cognitive psychology, for field studies in ecology, and for the use of regression models for observational data in econometrics. These lists should, ideally, be developed in consultation with both subject-matter experts and those who study how students learn. Thinking long-term and blue sky, it might even become possible—eventually—for meta-analyses to associate rates of failure to replicate with particular items in a subject area’s checklist.
In conclusion, then, I caution those of us who care about statistics and its teaching against becoming complacent. Some among us are old enough to remember the old-style textbooks filled with numerical recipes and fake data, before John Tukey’s Exploratory Data Analysis and Francis Anscombe’s Statistical Computing with APL. Other, younger colleagues may have been spared the courses that used to give statistics its skunk-at-the-picnic aroma. Regardless, however, despite the decades of important changes, we should not sit on our laurels. Much remains to be done.
Leave a Reply